Most benchmarks only record whether an agent succeeded. cua-speedrun is an evaluation system that also measures how long each task takes and what its model calls cost. Every leaderboard run uses the same pipeline and virtual machine setup on Modal, a pay-per-second cloud service, and one agent interface works across OSWorld, OSWorld 2.0, CUA-World, and MyPCBench. Smaller task sets, chosen so model rankings match the full benchmarks, keep repeated runs affordable.
Average time per task on the 50-task set, sped up 40×.
0:00.00
GPT-6 Astramedium
#11:30.289.6%
Gemini 3.8 Flashlow
#42:07.191.6%
Claude Opus 5high
#52:16.091.6%
Gemini 3.8 Flashmedium
#74:10.191.6%
Claude Sonnet 5high
#62:20.889.6%
Kimi K3max
#87:23.789.6%
GPT-5.6 Lunamedium
#21:40.681.6%
GPT-5.6 Solxhigh
#31:48.381.6%
Each lane is one model at one reasoning-effort setting, run by its included agent. Ticks mark its average number of steps. At the finish, each shows its average task time and score. Lanes are ranked by time only. The first to finish scores 89.6%. See the full OSWorld leaderboard
Same machine, same clock, any agent
cua-speedrun is the software that runs these comparisons. It holds the hardware, desktops, tasks, and timing fixed, so differences in time and cost come from the agent.
Off the clock
Start the agent and desktop sandboxes, reset the desktop for the task, run the agent's setup (init.py)
On the clock
Starts when the instruction is sentScreenshot, model call, keyboard and mouse actions, repeatedStops at done or the time limit
Off the clock
The benchmark's verifier scores the final state and trajectory
What each task's time includes. Agent time and environment time are recorded separately inside the timed interval.
Identical hardware for every run
Agents and desktops run in separate Modal sandboxes, built from the same pinned images for every run. Open-weight models are served with vLLM on fixed L40S GPUs. Results do not depend on whose computer launched the run.
One agent, four benchmarks
An agent is a folder with an agent.py that receives 1920×1080 screenshots and sends keyboard and mouse actions, and an init.py that sets it up. The same folder runs on OSWorld, OSWorld 2.0, CUA-World, and MyPCBench.
A clock that measures the agent
Setup and scoring happen off the clock. If a desktop or sandbox fails, the task is retried. If the agent crashes, the task counts as failed. Each agent reports its model cost after every request.
Inputs that do what they say
Our test tool, CUA-AutoDebug, sends 94 keyboard and mouse inputs to an app that records what arrives. PyAutoGUI over SSH, a common setup, got 11 wrong, such as typing > when < was requested. Our runtime got all 94 right, five times each.
Smaller task sets that keep the ranking
We chose 50 of 295 OSWorld tasks so that model rankings match the full benchmark. On models not used to choose them, the rank correlation is 0.98.
An optional Fast I/O mode
Fast I/O mode (FastCUA) cuts the delay between an action and the next screenshot from about 2–3 s to 2–28 ms, to test whether agents benefit from a faster desktop. Leaderboard results use the normal mode unless marked Fast I/O.
A faster environment, a slower agent. With Fast I/O on, GPT-6 Astra at low effort took 99.0 s per task instead of 89.5 s, averaged over five runs. Screenshots arrived before applications finished updating, so the agent looked again or repeated itself.
89.5 s99.0 s
+9.5 s
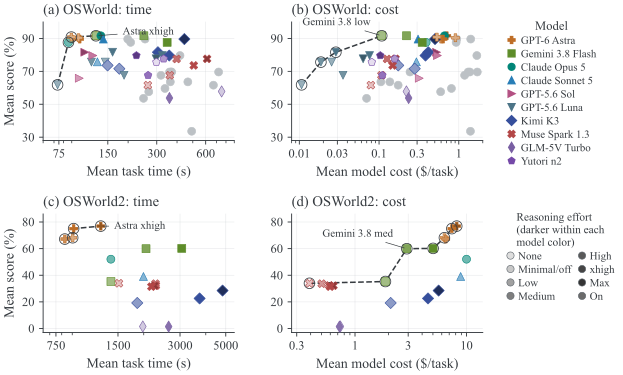
Same score, four times the wait. Kimi K3, an open-weight model, at max effort matches GPT-6 Astra at high effort on OSWorld (89.6%). For every open-weight model we tested, another model scored at least as high in less time, and another scored at least as high for less money.
101 s444 s
×4.4
Fewer tasks, similar ranking. A 50-task OSWorld subset, chosen so that historical scores match the full set, cuts evaluation time by 84.9%.
295 tasks50 tasks
−84.9%
More reasoning, less time. Gemini 3 Flash Preview on OSWorld, low to medium reasoning effort. The score also rose from 33.6% to 57.6%; extra thinking replaced repeated failed actions.
Interactive overview. Squares show task counts; each plotted point is a measured configuration, marked with its developer's logo. It covers the four task sets from our paper, and also includes results that are not in the paper's figures. Logos identify developers and are trademarks of their owners.
Evaluate your own agent
Start with an included agent or bring your own Python implementation. The toolkit prepares the desktops, runs benchmark tasks, and saves scores, timings, screenshots, and action logs. It supports OSWorld, OSWorld 2.0, CUA-World, and MyPCBench.
To start right away, open the notebook on Modal, fork it, and run its one cell. Or use the command line:
setup saves your Modal credentials and API keys. benchmark asks for an agent and a task set, then shows progress. Compute uses your Modal account and model calls use your API key.
The leaderboard covers the four task sets used in the paper. Compare models, filter them, and see each result's settings and cost. It also includes some results that are not in the paper's figures.
@misc{aggarwal2026cuaspeedrun,
  title  = {CUA-Speedrun: Standardized Benchmarking of the Speed of Computer-Use Agents},
  author = {Aggarwal, Pranjal and Jang, Lawrence Keunho and Welleck, Sean and Fried, Daniel and Salakhutdinov, Ruslan and Koh, Jing Yu},
  year   = {2026},
  url    = {https://arxiv.org/abs/2609.40284}
}